Semantic search in historical archives with AI
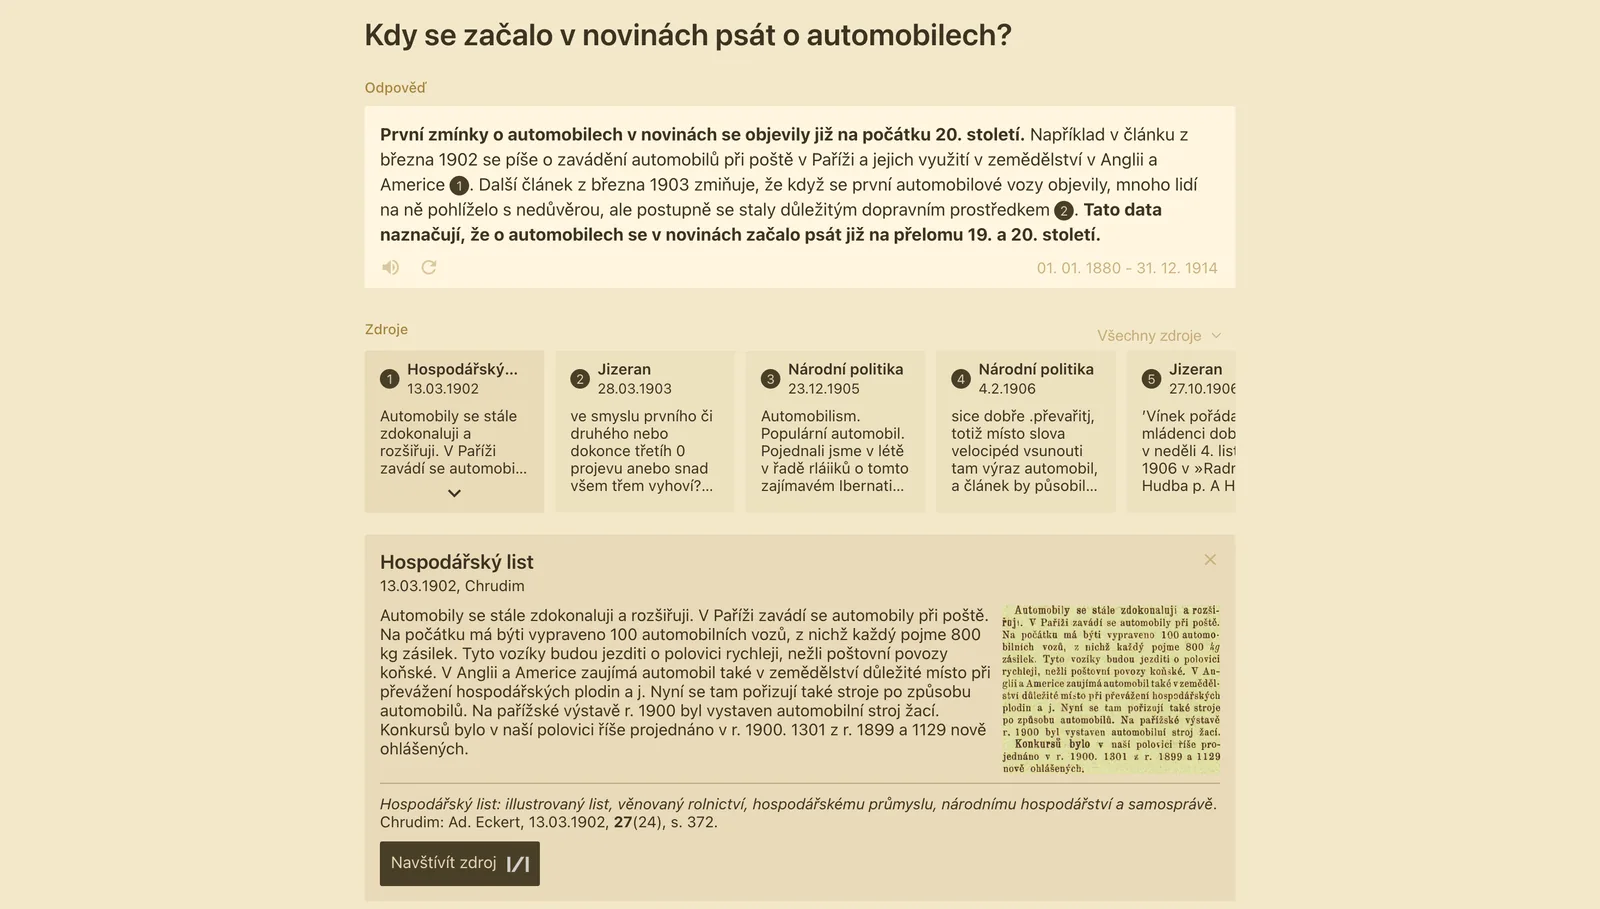
Paměť novin (Newspaper Memory) is an innovative application designed for advanced search and analysis of historical periodicals from the turn of the 19th and 20th centuries. Unlike conventional full-text search engines, which only work with exact keyword matches, this system uses large language models (LLMs) to understand the meaning and context of a query. It lets users discover events, relationships and period context in natural language, making work with extensive digital archives significantly more efficient.
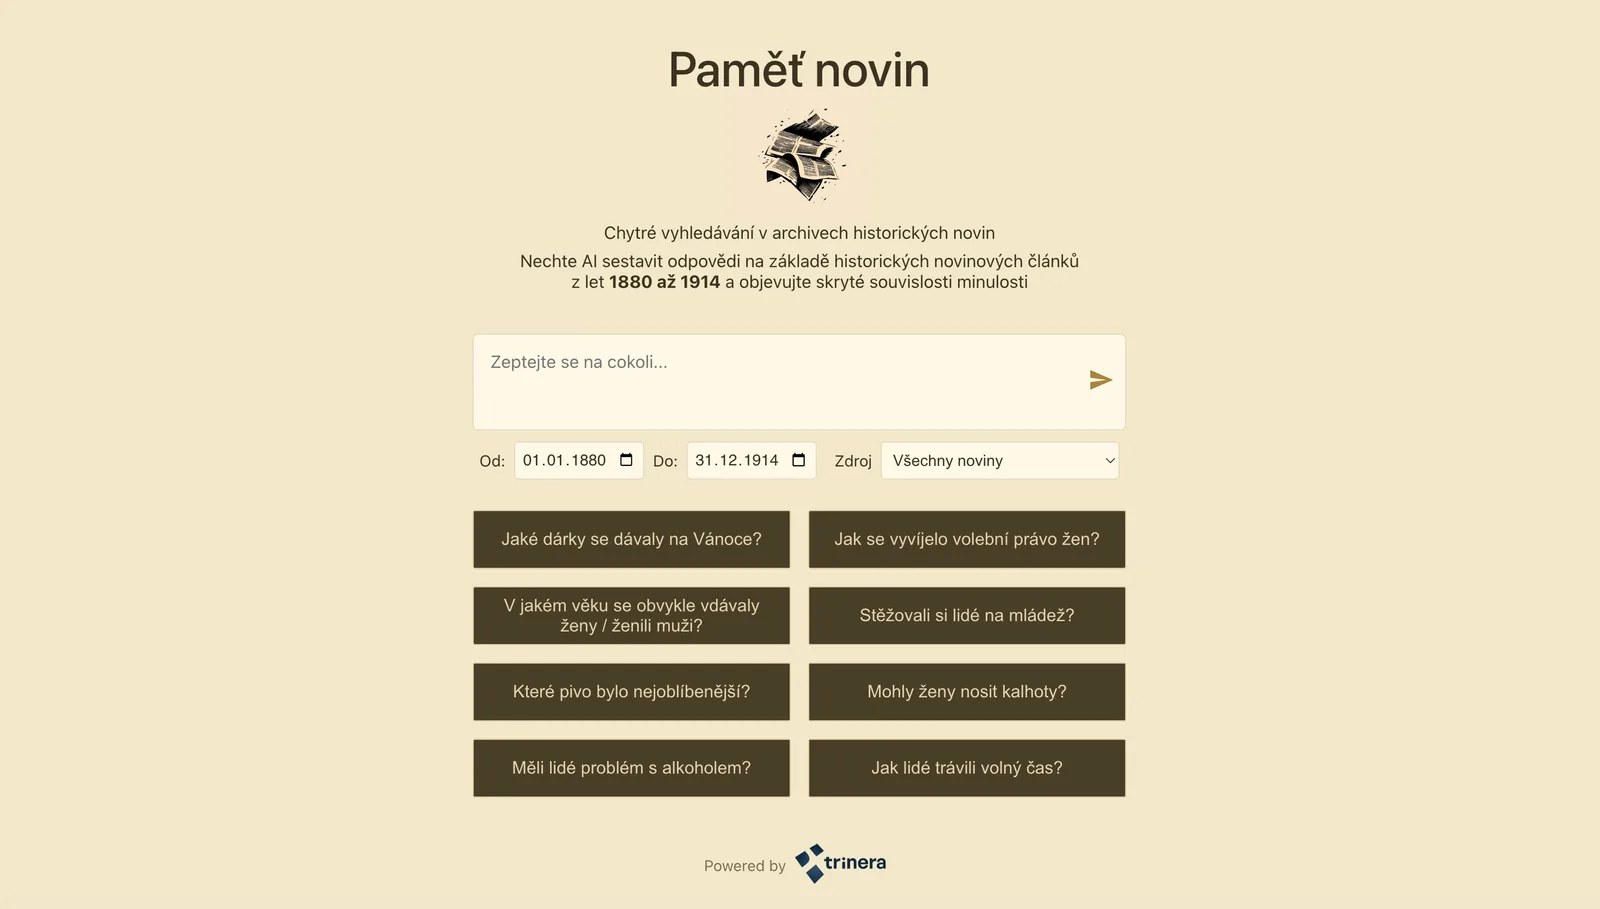
Our solution uses vector indexing and AI so that the system can answer users’ specific questions while providing direct links back to the source documents (a specific scan in the digital library). The integration of artificial intelligence (LLMs) ensures more accurate search results even for incomplete or imprecise queries.
Paměť novin does not just search for words — it interprets the content of articles, can summarize long texts and connect events across different newspaper titles. In this way, we transform a static digital archive into an active guide to history that can identify key topics and trends over time without complicated user training.
After all, try it yourself: www.pametnovin.cz
Using semantic querying in business practice
The core of the application, built on vector indexing and large language models (LLMs), enables efficient work with large sets of unstructured documents. Instead of a static website or an unreliable chatbot, you get a system that interprets the meaning of a natural-language query and immediately backs up its answers with a citation from a specific internal source.
Where can this technology be used?
- Managing corporate know-how: instant access to information in thousands of contracts, guidelines or technical sheets without manual searching.
- Intelligent customer support: a website that actually answers a customer’s question about a product or service based on the entire history of your documents.
- Data autonomy for management: the ability to analyze the content of archives and look for connections in the data independently, without waiting for IT to prepare scripts.
- Processing specialist texts: efficient research in archives of case law, project documentation or medical studies, where keyword search fails.
Blog
We have already written about Paměť novin — if you would like to know more, you can read about it on our blog: